
Question: How to count unique short sequences in FASTQ
0
gravatar for yjoechen
2.3 years ago by
yjoechen • 0
yjoechen • 0 wrote:

Hi, I wonder whether there is any tool that I could use to output the number of unique reads. I don't need any alignment to reference genome. Thanks!

bowtie galaxy • 1.0k views
ADD COMMENT • link • modified 2.3 years ago by Devon Ryan • 1.9k • written 2.3 years ago by yjoechen • 0
1
gravatar for Devon Ryan
2.3 years ago by
Devon Ryan • 1.9k
Germany
Devon Ryan • 1.9k wrote:

FastQC does that as part of its output. There's a graph of the number of reads that exist only once, twice, and so on.

ADD COMMENT • link written 2.3 years ago by Devon Ryan • 1.9k

Thanks for the advice, Devon Ryan! It seems that FastQC could be helpful. However, the default setting only reports overrepresented sequences with p >0.01. I wonder whether it is possible that we could extract the number counts of ALL unique sequences. Thanks.

ADD REPLY • link written 2.3 years ago by yjoechen • 0
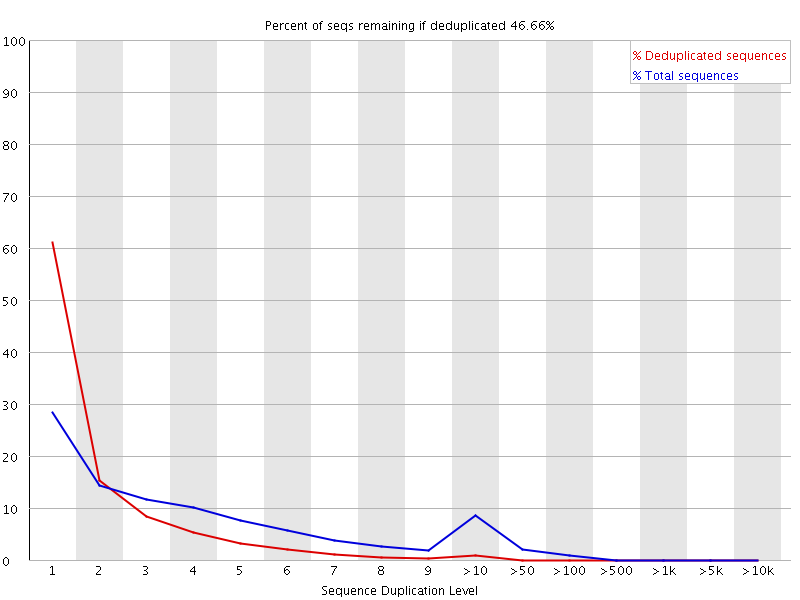
You're looking in the wrong section. You're looking for something that looks like this:

FastQC duplication levels example

You can get more details about that plot here

ADD REPLY • link written 2.3 years ago by Devon Ryan • 1.9k
Please log in to add an answer.

Help
Access

Use of this site constitutes acceptance of our User Agreement and Privacy Policy.
Powered by Biostar version 16.09
Traffic: 168 users visited in the last hour